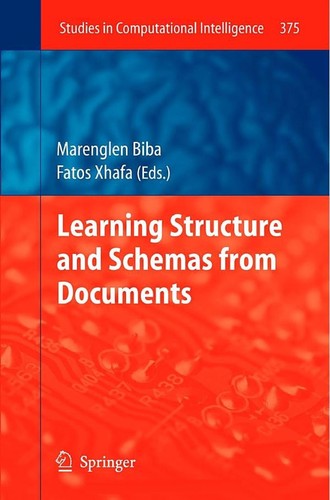
Learning Structure and Schemas from Documents
0
0
As an Amazon Associate and affiliate partner, Menrva Books earns from qualifying purchases. Learn more
Author Description
Author description coming soon. We're reaching out to them in the ether...
Menrva's Summary
THE THESIS
This book investigates the challenge of automatically extracting structured information and schemas from unstructured or semi-structured documents. It addresses the need for computational methods to understand and organize the vast amounts of data available in document form, proposing novel algorithms and techniques for schema induction and data extraction. The work is grounded in theoretical computer science principles and practical applications in areas like information retrieval and data mining.
THE SCOPE MAP
- Algorithms for schema induction from document collections.
- Techniques for extracting structured data from semi-structured and unstructured text.
- Methods for learning relational schemas from documents.
- Evaluation of proposed methods on real-world datasets.
- Discussion of applications in database construction and information retrieval.
THE AUTHORITY PERSPECTIVE
This work is positioned as a technical contribution to the field of data mining and information extraction, likely appealing to researchers and practitioners in computer science. Its focus on algorithmic development and theoretical underpinnings suggests a rigorous and detailed exploration of the subject matter. The book aims to provide a solid foundation for understanding and implementing automated document analysis techniques.
Page Count:
0
Publication Date:
2011-01-01
ISBN-10:
3642229123
ISBN-13:
9783642229121
Non-Fiction
Science & Technology
Art
Data Mining
Databases
Machine Learning
Computer Science
Information Retrieval
Community Tags
Similar Books